 A.I.
Chips
Chip families, with the stated compute on each page.
-
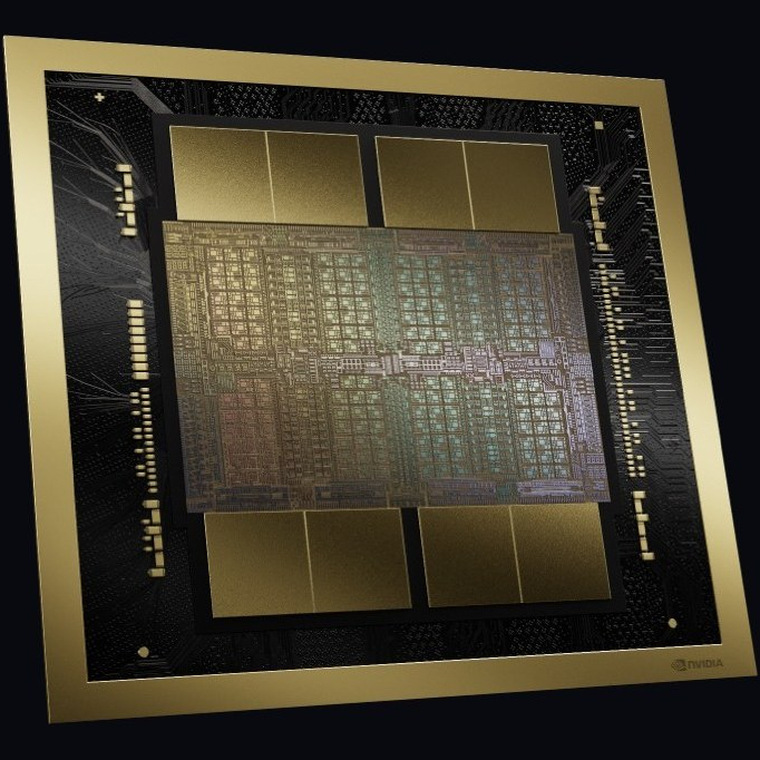
Blackwell
NVIDIANvidia's current GPU. 72 to a GB300 NVL72 rack.
- Chip
- Blackwell Ultra GPU
- Status
- Announced 18 Mar 2025
- Compute
- 10 PFLOPS FP8, sparse (dense not printed)
- Memory
- 279 GB HBM3E
- Bandwidth
- 8 TB/s
-
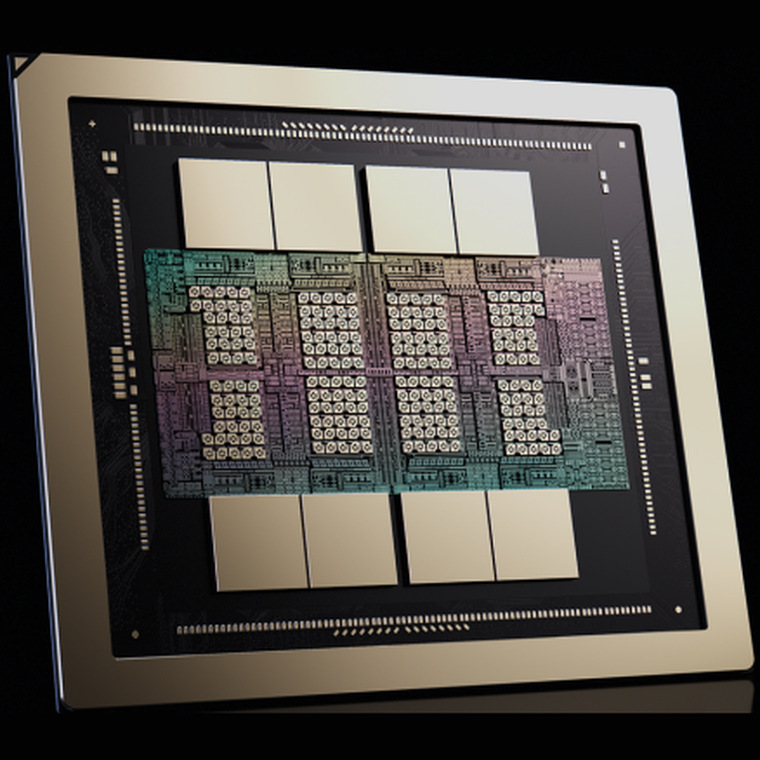
Rubin
NVIDIANvidia's next GPU, with 288 GB of HBM4. 72 to a Vera Rubin NVL72 rack.
- Chip
- Rubin GPU
- Status
- Announced 5 Jan 2026
- Compute
- 17.5 PFLOPS FP8, dense
- Memory
- 288 GB HBM4
- Bandwidth
- 19.2 TB/s
-
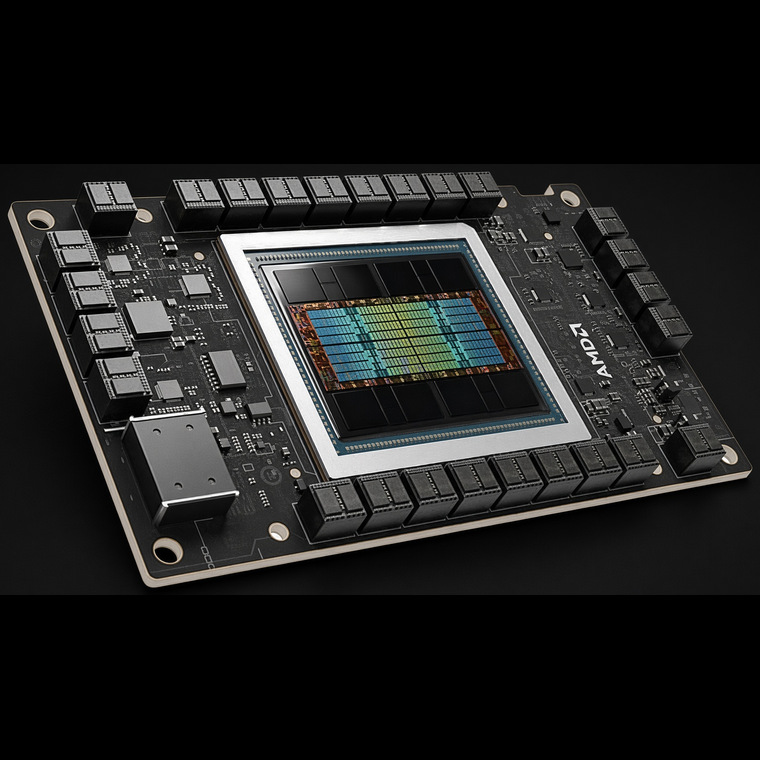 AMD Instinct MI350-series module
Instinct
AMDAMD's GPU line. A custom MI450 powers Meta's first gigawatt.
- Chip
- Custom MI450 GPU
- Status
- First shipments second half of 2026
- Compute
- not stated
- Memory
- not stated
- Bandwidth
- not stated
-
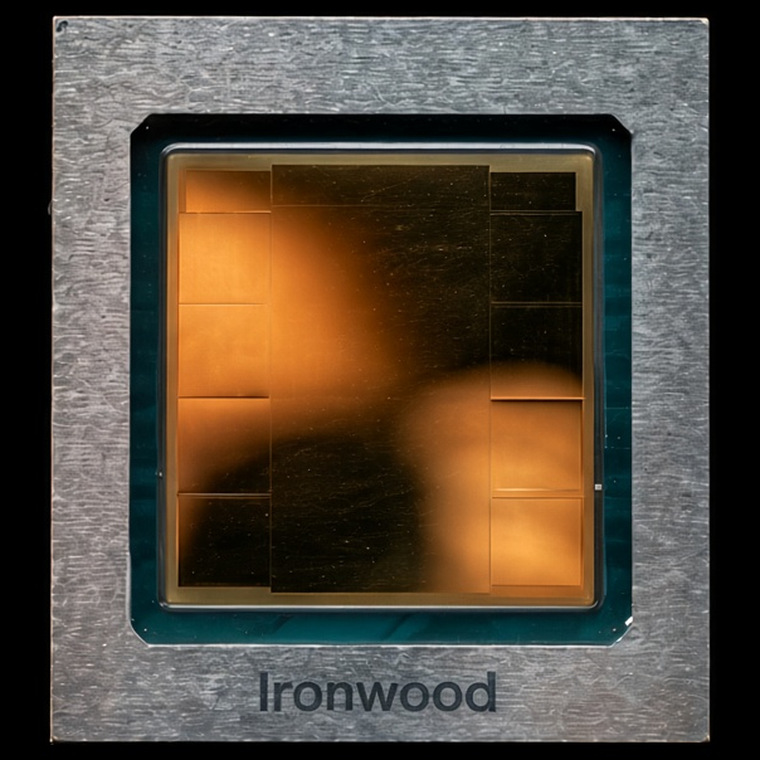
Ironwood
GoogleGoogle's seventh-generation TPU, rented by the chip-hour.
- Chip
- TPU7x
- Status
- Available 31 Mar 2026
- Compute
- 4.6 PFLOPS FP8
- Memory
- 192 GiB HBM
- Bandwidth
- 7.38 TB/s
- Price
- $12 per chip-hour, on demand, us-central1, Google list price
-
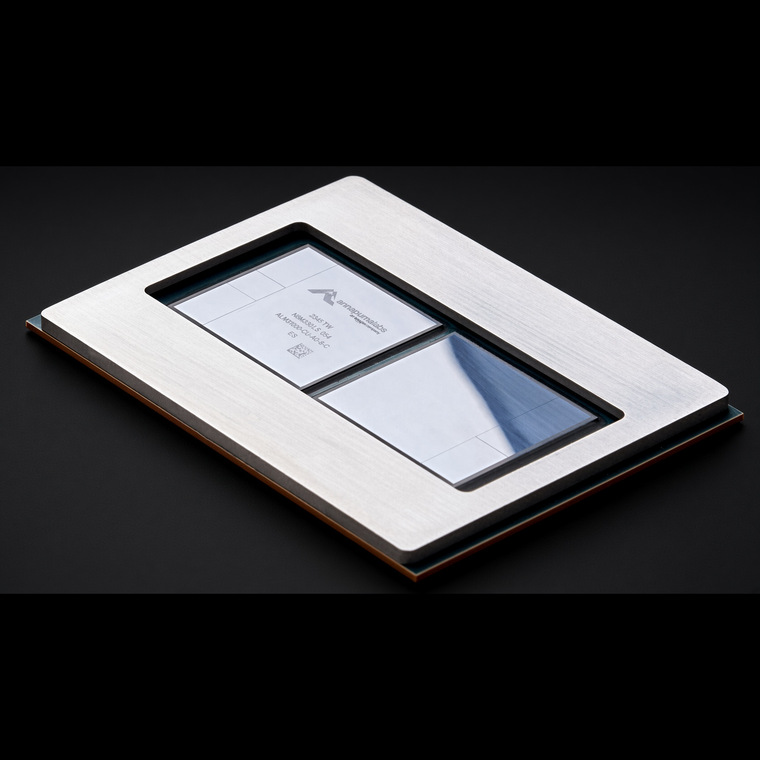
Trainium2
AWSAWS's own chip. Nearly 500,000 run Project Rainier for Anthropic.
- Chip
- Trainium2
- Status
- Available 3 Dec 2024
- Compute
- 1.3 PFLOPS FP8, dense
- Memory
- 96 GiB HBM
- Bandwidth
- 2.9 TB/s
-
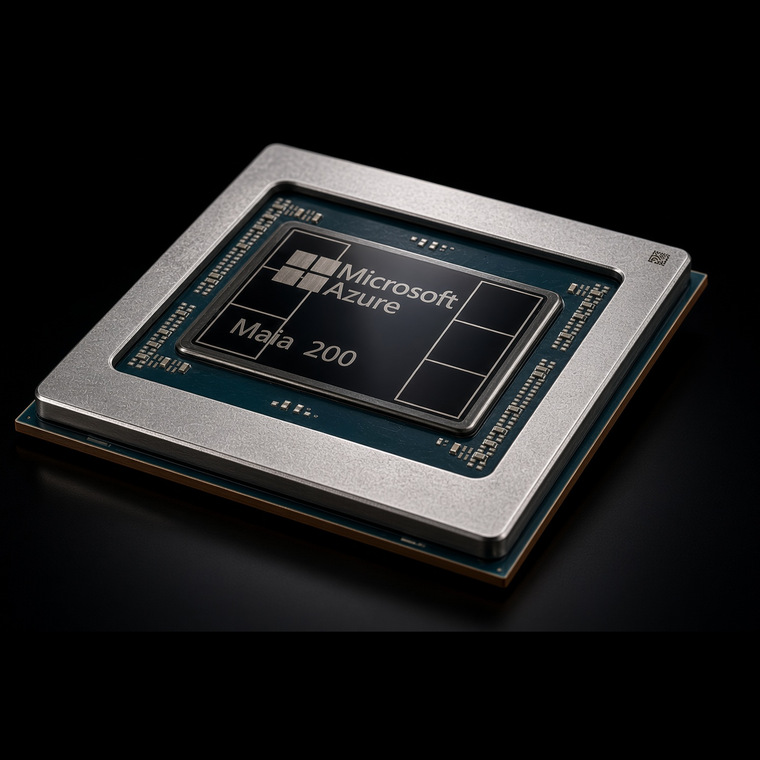
Maia 200
MicrosoftMicrosoft's inference chip. Maia 300 (288 GB HBM4, 18 TB/s) deploys from 2027.
- Chip
- Maia 200
- Status
- Announced 26 Jan 2026
- Compute
- Over 5 PFLOPS FP8
- Memory
- 216 GB HBM3e
- Bandwidth
- 7 TB/s
-
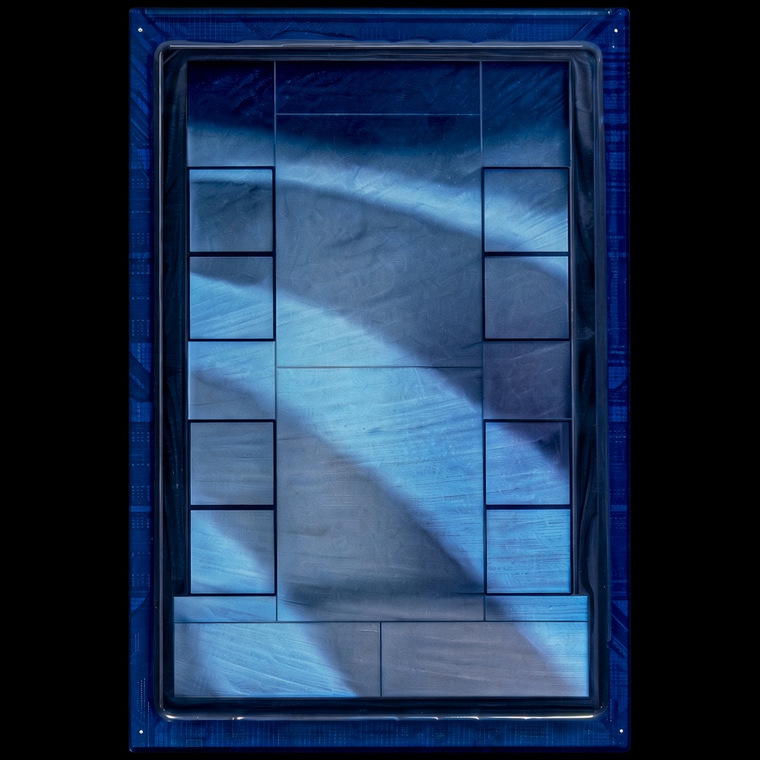
MTIA
MetaMeta's own chip family. The MTIA 300 is in production.
- Chip
- MTIA 300
- Status
- In production by 11 Mar 2026
- Compute
- not stated
- Memory
- 216 GB HBM3E
- Bandwidth
- not stated
-
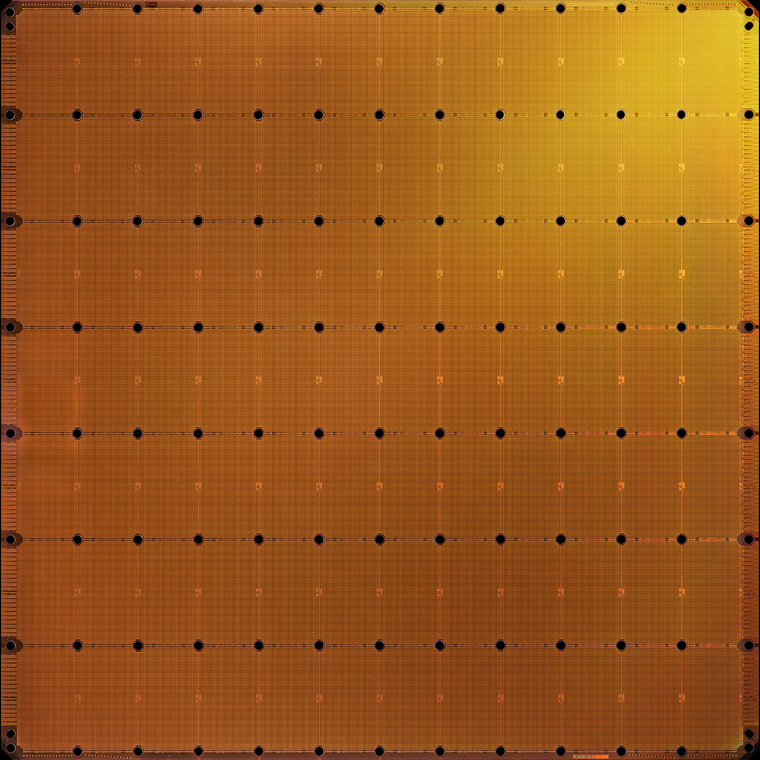
WSE-3
CerebrasOne chip the size of a whole silicon wafer.
- Chip
- WSE-3, one wafer
- Status
- Announced 13 Mar 2024
- Compute
- 125 PFLOPS peak AI, format not named
- Memory
- 44 GB on-chip SRAM
- Bandwidth
- not stated
-
Ascend 910C
HuaweiHuawei's AI chip. Up to 384 in one Atlas 900 A3 SuperPoD.
- Chip
- Ascend 910C
- Status
- In SuperPoDs since Mar 2025
- Compute
- 0.8 PFLOPS FP16, our division
- Memory
- 128 GB
- Bandwidth
- Up to 3.2 TB/s
-
Jalapeño
OpenAIOpenAI's first own inference chip, built with Broadcom.
- Chip
- Jalapeño
- Status
- Deploying by end of 2026
- Compute
- 13.4 PFLOPS MXFP4
- Memory
- 216 GiB HBM4
- Bandwidth
- 15.4 TB/s
-
Trainium3
AWSAWS's first 3nm AI chip. Up to 144 in a Trn3 UltraServer.
- Chip
- Trainium3
- Status
- Announced Dec 2025
- Compute
- 2.52 PFLOPS MXFP8
- Memory
- 144 GiB HBM3e
- Bandwidth
- 4.9 TB/s
-
TPU 8t and 8i
GoogleGoogle's eighth-generation TPUs: 8t trains, 8i serves.
- Chip
- TPU 8i
- Status
- Announced 22 Apr 2026
- Compute
- not stated
- Memory
- 288 GB HBM
- Bandwidth
- not stated
Google has not printed per-chip compute or bandwidth.
-
MI455X and Helios
AMDAMD's top Instinct GPU. 72 to a Helios rack.
- Chip
- Instinct MI455X
- Status
- Volume expected 2H 2026
- Compute
- 20.1 PFLOPS FP8
- Memory
- 432 GB HBM4
- Bandwidth
- 23.3 TB/s
-
Groq 3 LPX
NVIDIANvidia's SRAM inference rack. 256 LPUs beside Vera Rubin.
- Chip
- Groq 3 LPU
- Status
- In full production 24 Aug 2026
- Compute
- 1.2 PFLOPS FP8, our division
- Memory
- 500 MB on-chip SRAM
- Bandwidth
- 150 TB/s SRAM
Partnerships and stacks Meta stack · Meta and Nvidia · Meta and Broadcom · Meta and AMD · Terafab, the SpaceX and Tesla chip factory