 A.I.
Hardware · Chips
Rubin
Rubin is the NVIDIA GPU family that follows Blackwell. One Rubin GPU delivers 50 PFLOPS of NVFP4 inference and carries 288 GB of HBM4. The Vera Rubin NVL72 is the rack built around it, with 72 Rubin GPUs and 36 Vera CPUs. Meta's purchase is on the Meta stack.
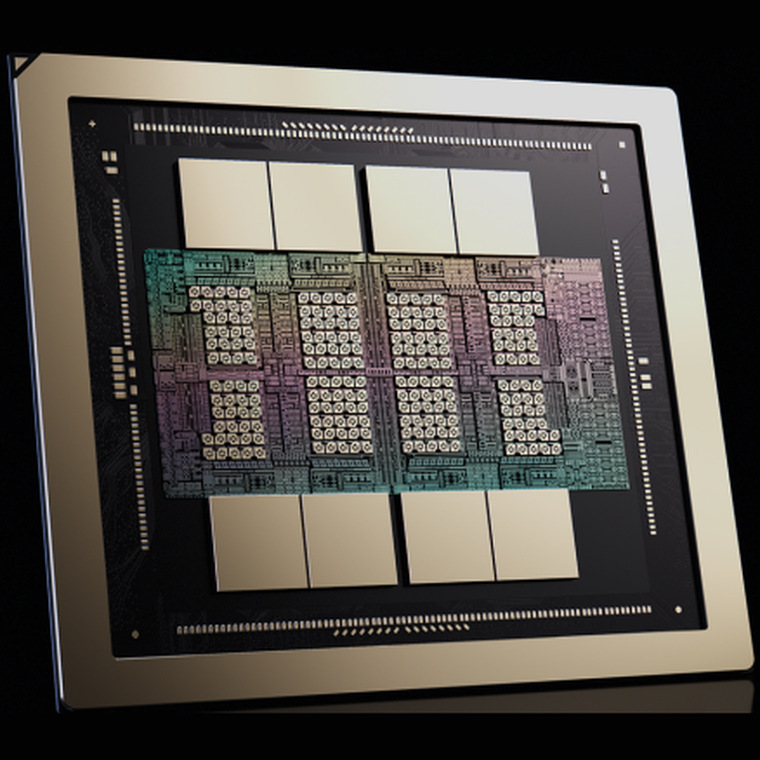
Rubin GPU
NVIDIA announced Rubin on 5 January 2026. The Rubin GPU delivers 50 petaflops of NVFP4 compute for AI inference, which is running a trained model to answer requests. NVFP4 is NVIDIA's 4-bit number format, and a petaflop is a thousand trillion math operations per second. Compared with the Blackwell platform, NVIDIA says Rubin cuts the cost of each inference token by up to 10 times, where a token is a small chunk of text. It also says Rubin needs 4 times fewer GPUs to train mixture-of-experts models, which split the work among many smaller expert networks inside one model. These are NVIDIA's own claims. NVIDIA says Rubin is in full production and that partners will offer Rubin-based products in the second half of 2026.
| Figure | Rubin GPU |
|---|---|
| NVFP4 inference | 50 PFLOPS, sparse |
| NVFP4 training | 35 PFLOPS, dense |
| FP8/FP6 training | 17.5 PFLOPS, dense |
| FP16/BF16 | 4 PFLOPS, dense |
| TF32 | 2 PFLOPS, dense |
| FP32 | 130 TFLOPS |
| FP64 | 33 TFLOPS |
| Memory | 288 GB HBM4 at 19.2 TB/s |
| NVLink (GPU-to-GPU link) | 3 TB/s |
| Networking | 0.45 TB/s |
Training is teaching a model. Sparse figures count a shortcut that skips zeros in the math, so they read higher, and dense figures count every number. FP8 stores each number in 8 bits and FP6 in 6 bits. FP16, BF16, TF32, FP32, and FP64 are larger number formats that are more precise but slower. HBM4 is the fourth generation of high-bandwidth memory, the fast memory stacked next to the chip. NVLink is NVIDIA's wiring that lets GPUs share work.
Vera Rubin NVL72
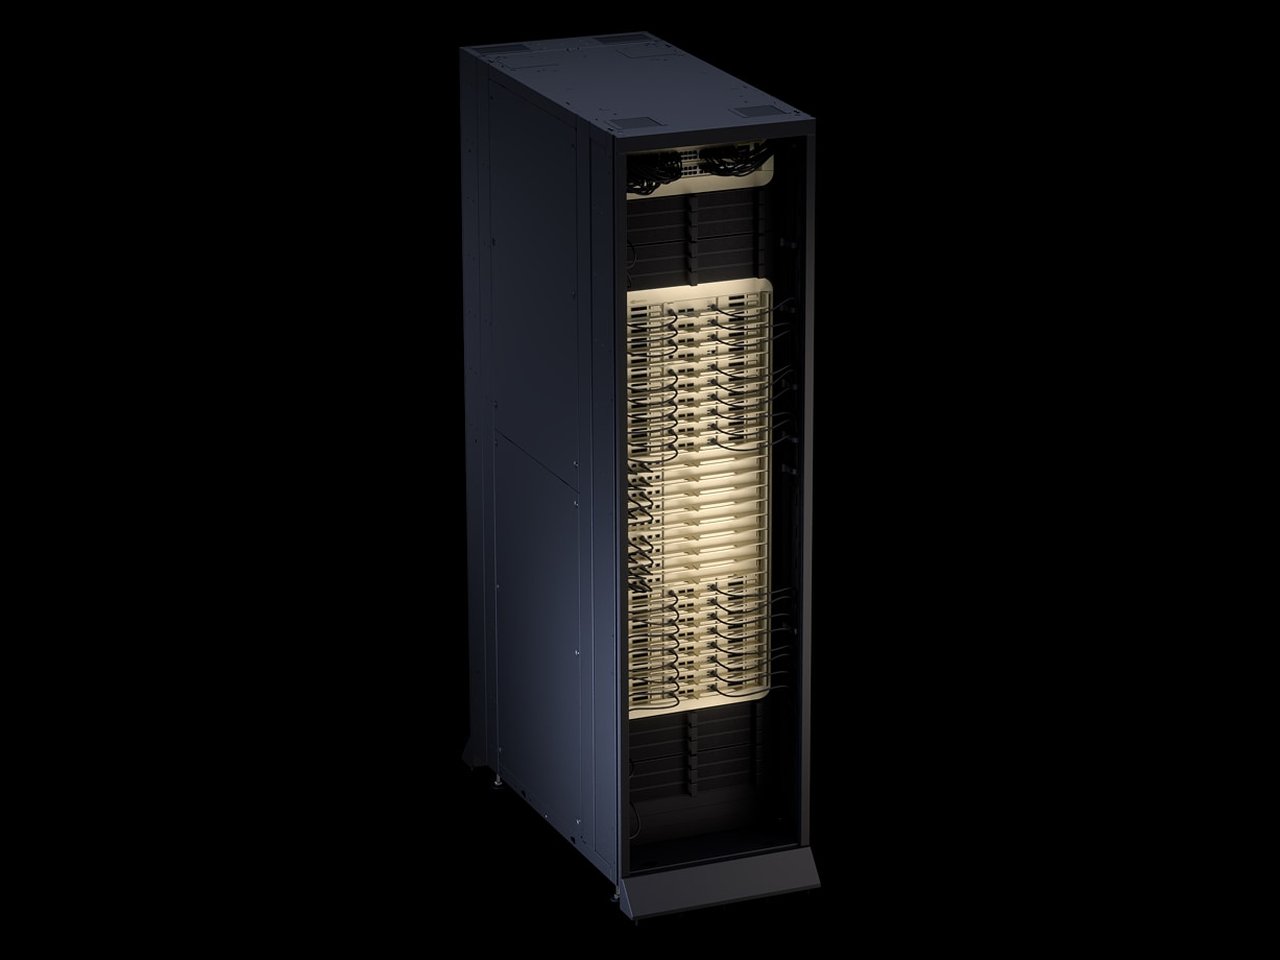
The 5 January 2026 release says the Vera Rubin NVL72 combines 72 Rubin GPUs, 36 Vera CPUs, and NVLink 6, the sixth generation of NVIDIA's chip-to-chip wiring. It is a rack-scale system, meaning the whole server rack is built as one machine.
| Figure | Vera Rubin NVL72 |
|---|---|
| GPUs | 72 Rubin |
| CPUs | 36 Vera |
| CPU | 3,168 Olympus cores and 6,336 threads |
| NVFP4 inference | 3,600 PFLOPS |
| NVFP4 training | 2,520 PFLOPS |
| FP8/FP6 training | 1,260 PFLOPS |
| FP16/BF16 | 288 PFLOPS |
| TF32 | 144 PFLOPS |
| FP32 | 9,360 TFLOPS |
| FP64 | 2,400 TFLOPS |
| GPU memory | 20.7 TB HBM4 at 1,400 TB/s |
| NVLink | 216 TB/s |
| NVLink-C2C | 65 TB/s |
| CPU memory | Up to 54 TB LPDDR5X |
| Networking | 32.4 TB/s |
| Inlet temperature | 45°C |
On NVIDIA's product page, the inference figures are sparse, and the training, FP16, BF16, and TF32 figures are dense. The networking bandwidth counts traffic in both directions. Olympus is NVIDIA's own CPU core design. NVLink-C2C is the link between each Vera CPU and its GPUs. LPDDR5X is a low-power type of memory used by the CPUs. Inlet temperature is how warm the cooling liquid can be when it enters the rack.