 A.I.
Hardware · Chips
Trainium2
Trainium2 is the second-generation AI chip from Annapurna Labs, Amazon's in-house chip design team. AWS, Amazon's cloud business, rents it out as cloud servers. Despite the name, it handles both training, which is teaching a model, and inference, which is running it to answer requests. Anthropic trains and runs Claude on it in Project Rainier.
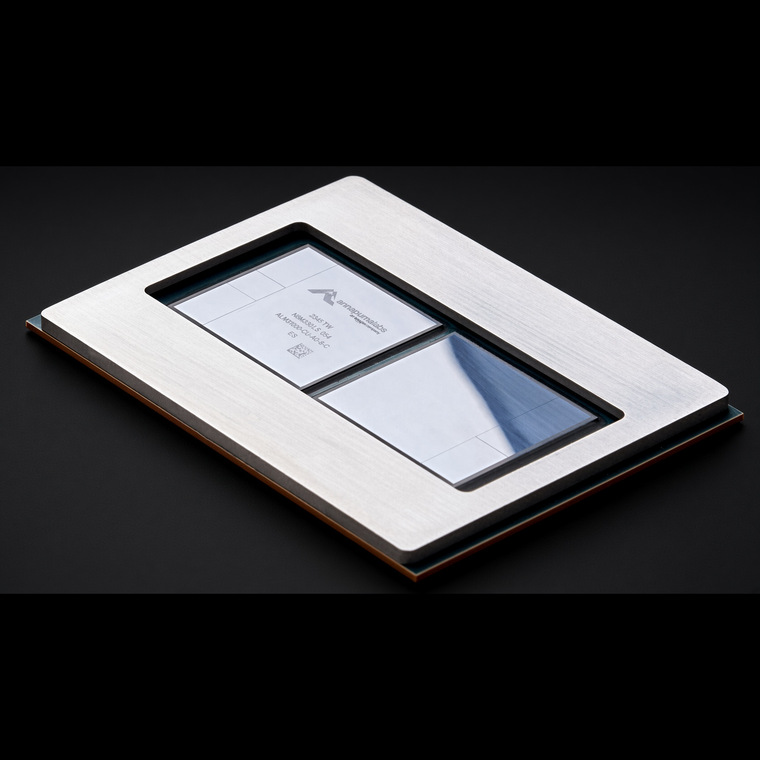
The chip
AWS announced Trainium2 on 28 November 2023 at re:Invent, its yearly cloud conference, and said it would train models up to 4 times faster than the first Trainium (AWS, 28 November 2023). Trn2 instances, the rentable servers built on it, became generally available on 3 December 2024 (AWS News Blog, 3 December 2024).
| Figure | One Trainium2 chip |
|---|---|
| NeuronCores | 8 |
| Dense FP8 | Up to 1.3 PFLOPS |
| Sparse FP8 | Up to 5.2 PFLOPS |
| Memory | 96 GiB HBM |
| Memory bandwidth | 2.9 TB/s |
| Chip-to-chip link (NeuronLink) | 1 TB/s |
A NeuronCore is one of the chip's compute engines. FP8 stores each number in 8 bits. A PFLOPS is a thousand trillion math operations per second. Dense counts every number. Sparse counts a shortcut that skips zeros, which is why it reads four times higher. HBM, or high-bandwidth memory, is the fast memory stacked next to the chip. NeuronLink is AWS's own wiring between chips. All figures are from the 3 December 2024 AWS post.
Servers
Trainium2 is rented in two sizes (AWS, Amazon EC2 Trn2 instances).
| Figure | Trn2 instance | Trn2 UltraServer |
|---|---|---|
| Trainium2 chips | 16 | 64 |
| Dense FP8 | 20.8 PFLOPS | 83.2 PFLOPS |
| HBM | 1.5 TB | 6 TB |
| HBM bandwidth | 46 TB/s | 185 TB/s |
| Network (EFAv3) | 3.2 Tb/s | 12.8 Tb/s |
An UltraServer is four Trn2 instances joined by NeuronLink so 64 chips work as one machine. EFA is the AWS network that links servers to each other. AWS says Trn2 instances give 30% to 40% better price performance than its GPU-based P5e and P5en servers, and are 3 times more energy efficient than first-generation Trn1. Those are AWS's own claims.
Project Rainier
On 29 October 2025 AWS said Project Rainier, a cluster it built with Anthropic across several US data centers, was fully running with nearly 500,000 Trainium2 chips (Amazon, AWS activates Project Rainier). AWS said it gives Anthropic more than five times the compute it used to train its earlier models, and that Claude was expected to run on more than 1 million Trainium2 chips, for training and inference, by the end of 2025.
What comes next
Trainium3 is the next generation. AWS's Trainium page says it has 144 GB of HBM3e per chip at 4.9 TB/s, 1.7 times the memory bandwidth of Trainium2, and up to 2 times the MXFP8 compute. Its UltraServers hold up to 144 chips (AWS Trainium). Its full figures are on the Trainium3 page.